
Autonomous exploratory testing is an unscripted software validation approach in which AI agents dynamically interact with an application using reasoning rather than predefined scripts. Instead of following documented paths, these systems leverage heuristic-based exploration and context-awareness to navigate complex interfaces, map undocumented application states, and surface the “unknown unknowns” that structured testing consistently misses.
Unlike traditional automation, which validates only what engineers anticipated, autonomous agents operate as curiosity-driven systems — probing boundaries, correlating visual anomalies with functional failures, and continuously updating a live state machine model of the software under test. In 2026, this approach became a production discipline, not a research experiment. Teams that have adopted agentic QA report fundamentally different defect profiles at release: fewer escaped edge cases, more coverage of unintentional interaction paths, and dramatically reduced reliance on manual exploratory sessions.
According to McKinsey’s October 2025 analysis of AI-centric software organizations, companies that have fully embedded AI into their operational workflows are reporting 20 to 40 percent reductions in operating costs, driven primarily by automation, faster development cycle times, and more efficient allocation of engineering talent. While that figure spans the full software organization, testing infrastructure (historically one of the heaviest sources of maintenance overhead) is a primary driver of that cost compression when autonomous agents replace brittle script libraries.
Separately, the Stack Overflow 2024 Developer Survey (drawing on responses from more than 65,000 developers across 185 countries) found that 80% of developers anticipated AI tools would become more deeply integrated into how they test code within the following year, ranking code testing as the single most anticipated area of AI workflow expansion alongside documentation. That adoption curve shows no signs of plateauing: as autonomous exploratory agents mature in capability and drop in cost through 2026, the developer appetite the survey captured is translating into production deployments, not just planned evaluations.
At a Glance
Autonomous Exploratory Testing in 2026
What AI agents find that scripts never could.
Approach: Heuristic-based, unscripted exploration — agents navigate without requirement documents
Coverage target: Unknown unknowns — undocumented pathways, edge-case permutations, unintended interactions
Speed advantage: 1,000+ edge-case permutations scanned in the time a human tests one happy path
Visual layer: Autonomous diffing correlates layout regressions with functional failures in real time
Integration: Discovered defects auto-logged as structured tickets in GitHub Issues and Jira
Cost impact: Script maintenance overhead eliminated; QA engineer time reallocated to strategic oversight
“Autonomous exploration does not validate what you planned — it discovers what you missed. In 2026, that distinction became the difference between resilient software and escaped production failures.”
What Changed in 2026: Why Did AI Move From Executing Scripts to Exploring Applications?
The 2026 inflection point arrived when AI reasoning capability crossed the threshold required to infer application intent from visual context alone — without structured test inputs. Agents no longer need a requirement document; they observe the interface, model the underlying business logic, and begin probing for states the development team never mapped.
For the previous decade, the testing industry operated under a damaging premise: that automation equaled quality. Teams invested thousands of engineering hours writing Playwright and Selenium scripts that could only confirm what developers already knew — that the happy path worked. These scripts were precise instruments pointed at the wrong target. They validated the expected. They ignored the possible.
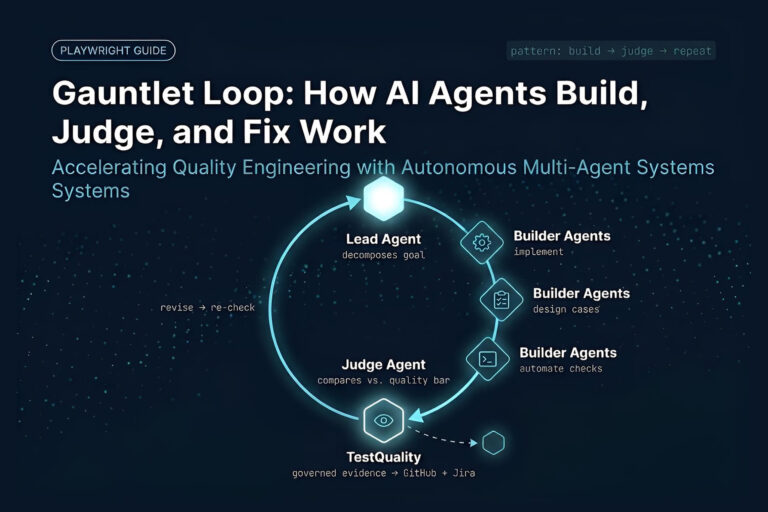
The 2026 transition dismantled this model. Cloud compute costs fell to the point where running a persistent AI agent against a staging environment cost less than one hour of a QA engineer’s time. Simultaneously, multimodal model capability matured enough that agents could interpret a rendered interface — not just parse its DOM — and make contextual decisions about where to probe next. GitHub Actions pipelines gained native support for agent orchestration hooks, meaning autonomous exploratory runs could trigger on every pull request without manual scheduling.
The result: engineering teams stopped treating exploratory testing as a luxury sprint activity reserved for senior testers. It became a continuous, automated layer in the CI/CD pipeline — running in parallel with unit and integration tests, reporting directly into TestQuality dashboards, and filing structured defect tickets in Jira before a human reviewer ever opened the branch.
Key Takeaway for Managers: Retire the metric of “automated test count.” In 2026, software resilience is measured by your testing infrastructure’s ability to independently navigate the application and surface failures you never explicitly programmed it to find.
How Is Agentic Exploration Different From Monkey Testing and Traditional Fuzzing?
Agentic exploration applies curiosity-driven reasoning to software navigation — each action is informed by what the agent observed in the previous state. Monkey testing and fuzzing inject randomized inputs with no contextual model of the application, generating high noise and low actionable signal. The difference is not speed — it is intelligence.
Traditional fuzzing was the testing industry’s best approximation of unscripted validation. Developers injected randomized binary strings into form fields and API endpoints, hoping the resulting chaos would surface a crash. Occasionally it did. More often it generated thousands of meaningless error logs that buried the one genuine vulnerability inside an ocean of noise.
Agentic exploration operates on an entirely different cognitive model. When an agent encounters a form field, it reads the label, infers the expected data type, consults its accumulated state model, and then constructs a sequence of targeted edge-case inputs — empty string, maximum character length, SQL injection pattern, Unicode boundary character — each designed to expose a specific class of vulnerability. It does not hammer randomly. It probes deliberately.
The state machine discovery layer compounds this advantage. As the agent navigates, it builds a live graph of application states — which actions unlock which views, which conditions trigger which error paths, which UI components are mutually dependent. By the time a human tester has completed one exploratory session, the agent has mapped dozens of previously undocumented state transitions and flagged the anomalies for review inside TestQuality.
Key Takeaway for Managers: Stop paying for compute that blindly hammers your application. Agentic workflows apply deliberate, calculated pressure to your most vulnerable system boundaries — and they document every finding automatically.
How Do AI Agents Actually Discover the “Unknown Unknowns” That Humans Miss?
AI agents discover unknown unknowns by constructing a dynamic state machine model during execution — mapping undocumented application pathways as they navigate, then deliberately stress-testing the boundaries between those states. Every anomalous response updates the model and generates a new probe sequence targeting the surrounding logic.
The most catastrophic production failures share a common origin: they emerge from the unintentional intersection of two features that were tested in isolation but never together. A discount code applied simultaneously with a loyalty point redemption. A session timeout triggered mid-upload. A timezone conversion error that only surfaces on specific locale settings during daylight saving transitions. No requirement document describes these scenarios because no one anticipated them.
Autonomous agents find them because they are not constrained by human mental models. When evaluating raw discovery performance, the gap between agent and human capability is structural, not marginal:
- Scanning 1,000+ edge-case permutations in the time a human tests one happy path
- Maintaining perfect contextual memory of all previously visited application states across multi-step workflows
- Instantly correlating frontend visual anomalies with backend API error responses in the network log
- Executing heuristic-based exploration across parallel browser sessions simultaneously without cognitive fatigue or confirmation bias
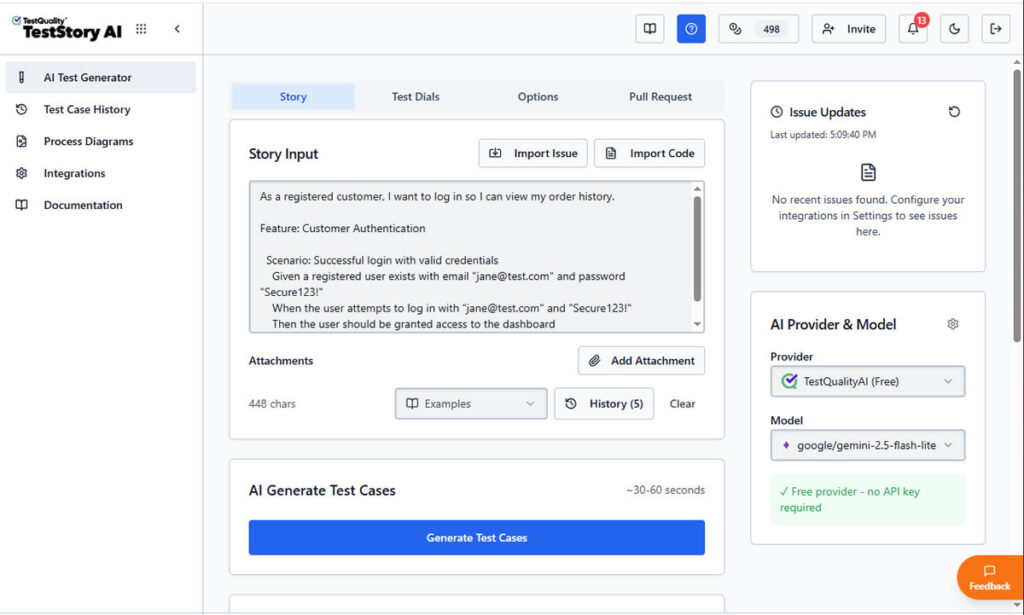
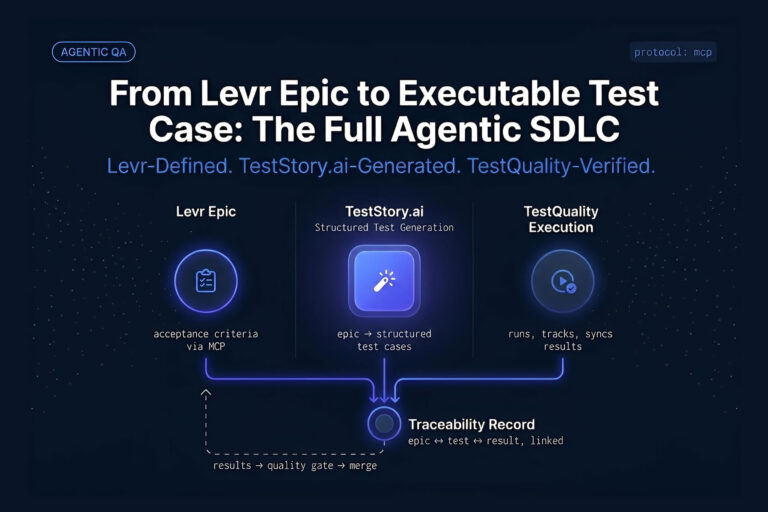
A raw user story entered into TestStory.ai is interpreted by the agentic layer in real time. Rather than waiting for a QA engineer to decompose requirements into test cases manually, the agent infers the acceptance boundaries, constructs edge-case scenarios the story did not explicitly describe, and surfaces them as structured, executable test cases — ready to sync directly into TestQuality.
Human testers suffer from what cognitive scientists call “creator bias” — they unconsciously navigate software the way it was designed to be used. They confirm intent. AI Agents possess no such bias. They explore intent boundaries, and the vulnerabilities live precisely at those boundaries.
Key Takeaway for Managers: The defects that reach production are not the ones your team failed to write scripts for — they are the ones your team failed to imagine. Only agents without human assumptions can find them systematically.
What Is Autonomous Visual Diffing and Why Can’t DOM-Based Tests Catch What It Catches?
Autonomous visual diffing enables agents to detect UI regressions that exist in the rendered interface but are invisible to DOM-level test assertions. A button can be present in the HTML and simultaneously unreachable by a user, and only pixel-level visual analysis catches the overlap that made it non-interactive.
Modern web applications are visually dense and aggressively responsive. A single CSS specificity conflict can push a primary CTA button beneath a non-interactive overlay. The DOM reports the button as present. The unit test passes. The user cannot click it. Traditional Playwright and Selenium scripts, operating purely at the DOM layer, miss this class of failure entirely because they verify element existence, not element accessibility within the rendered viewport.
Multimodal agents evaluate applications the way human retinas do. By layering visual regression analysis over active exploration, the agent identifies when a modal component obscures a form submission input. Rather than logging a static screenshot, it dynamically adjusts its navigation strategy — attempting to interact with the obscured element, confirming the functional blockage, and then escalating the finding with full context: the visual diff, the reproduction sequence, and the network log at the moment of failure.
As detailed in our comparison of AI test tools for Jira blog post, these autonomous systems attach visual diffing evidence directly to the defect ticket inside Jira by eliminating the ambiguity that plagues standard QA bug reports and giving developers everything they need to reproduce and resolve the issue immediately.
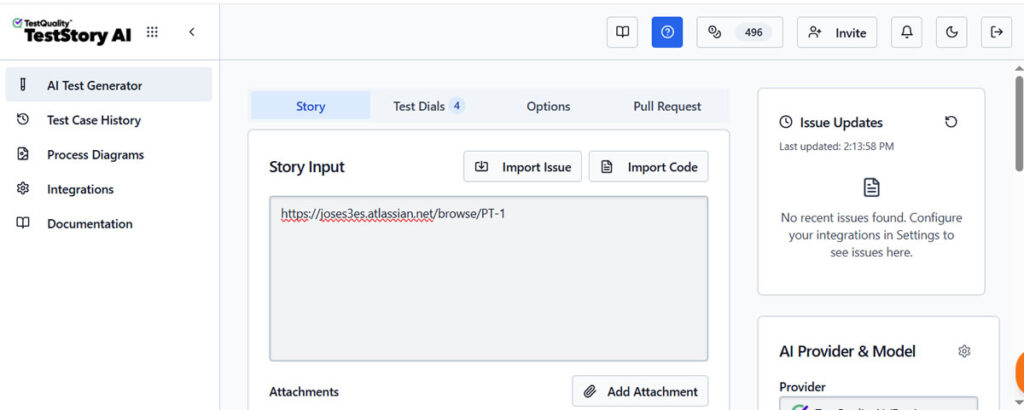
A Jira issue URL is pasted directly into TestStory.ai and, no requirement document, no manual test plan, no scripted input template. The agent fetches the issue context from Jira autonomously, interprets the feature scope, and begins reasoning about the full risk surface the issue introduces.
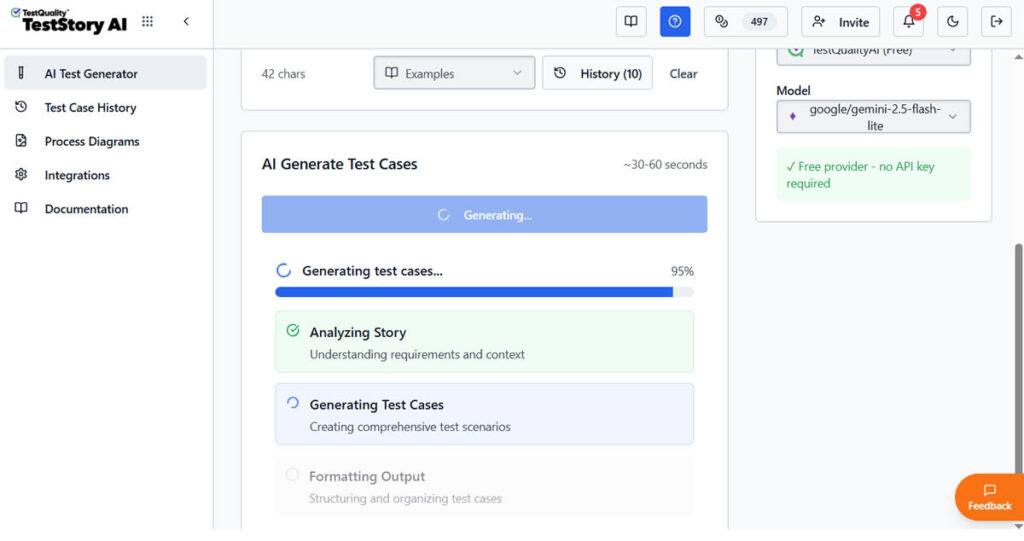
TestStory.ai in action, the agent actively fetching and reasoning about the Jira issue context at 95% completion. Behind this progress indicator, the agent is interpreting the feature scope, mapping the risk surface, and constructing the full test case set before a single test has been manually written.
What the developer logged as a single task becomes the seed for a complete, multi-type test coverage set.
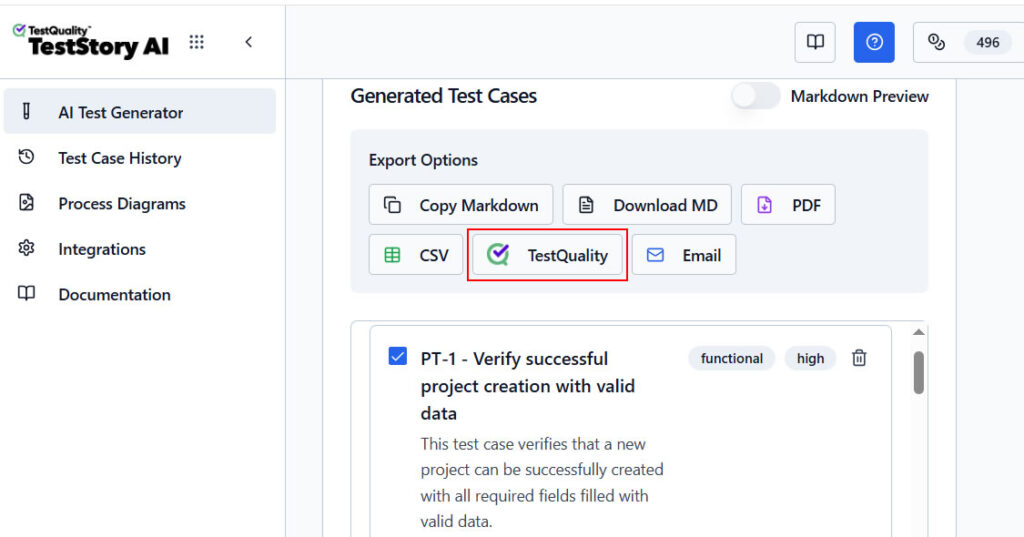
With test cases generated, a single click exports the full output into TestQuality, where the real test management workflow begins. From there, teams can execute the test cases within a dedicated test cycle, log new Jira issues directly from a failed result, comment on the originating Jira issue, or reassign it to another team member. The entire quality loop, from Jira issue to test execution to resolution, closes without leaving the integrated workflow.
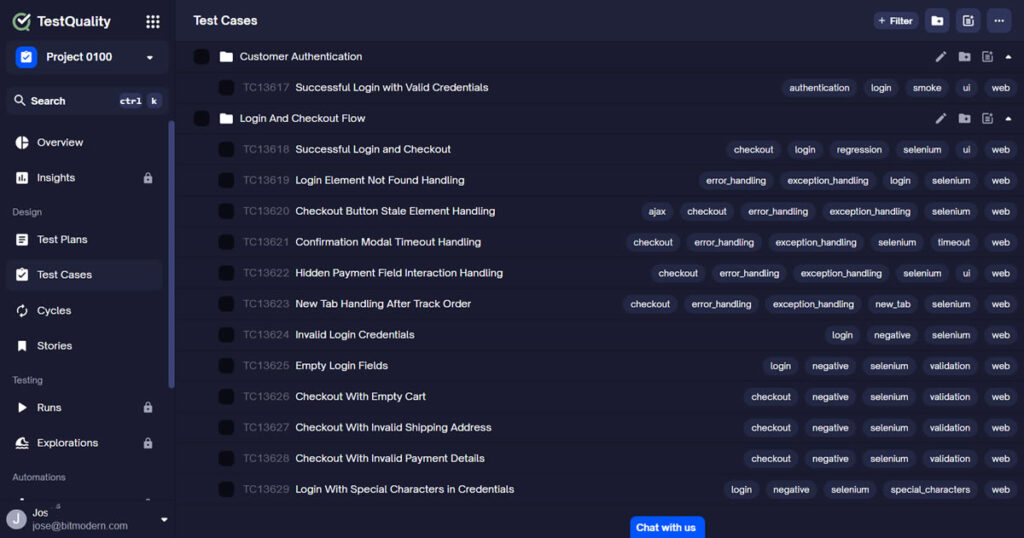
Once exported into TestQuality, the generated test cases appear in the repository tree under their originating Jira issue, fully structured, assignable, and ready for execution. Results sync bidirectionally back into Jira, giving development teams complete traceability from requirement to test outcome without leaving their existing workflow.
Key Takeaway for Managers: If your testing strategy cannot catch a bug that exists visually but not in the DOM, you have a coverage blind spot that only multimodal agents can close.
Stop Waiting for Users to Find Your Edge Cases
Generate, Export, and Track Test Cases Without Writing a Single Script.
TestStory.ai generates structured test cases from your Jira issues and user stories — covering functional, negative, security, and boundary scenarios your requirements never explicitly described. Export directly into TestQuality for execution, tracking, and bidirectional Jira sync.
What Does Autonomous Exploratory Testing Actually Cost Compared to Manual QA?
Autonomous exploratory testing eliminates script maintenance overhead — historically 25-30% of QA sprint capacity — and redirects that engineering time toward strategic product decisions. The primary cost shifts from human labor hours to cloud compute, and compute costs at scale are predictable, parallelizable, and declining.
The financial case for abandoning legacy automation frameworks is built on defect escalation economics. Research from IBM’s Systems Sciences Institute established the foundational benchmark: a defect found in production costs up to 100 times more to remediate than one caught during the design or staging phase. Autonomous agents deployed continuously in CI/CD pipelines — triggering on every GitHub pull request, reporting results into TestQuality before merge — systematically flatten this cost curve by moving discovery earlier in the development cycle.
The comparative economics across methodologies:
| Capability Dimension | Manual Exploratory QA | Automated QA (Playwright / Selenium) |
Agentic QA (TestStory.ai) |
|---|---|---|---|
| Unknown Unknown Discovery | Limited — bounded by human session speed and bias | None — only validates pre-scripted known paths | Continuous — agent maps undocumented state intersections autonomously |
| Edge Case Coverage | Dependent — bounded by engineer experience and session time | Only — what was explicitly scripted in advance | Inferred — 1,000+ permutations scanned per session without fatigue |
| Visual Regression Detection | None — manual spot checks only, no systematic coverage | Pixel-diff only — DOM-invisible regressions missed entirely | Semantic — correlates layout shifts with functional failures in real time |
| Script Maintenance Overhead | None — no scripts to maintain | Very High — ~25-30% of QA sprint capacity consumed by upkeep | Zero — self-healing, dynamic, no selector maintenance required |
| State Machine Discovery | Partial — constrained by creator bias and session duration | None — executes fixed paths, no dynamic state mapping | Continuous — live graph updated with every navigation decision |
| Jira Integration | Manual — engineer logs issues and links tests manually | Manual — custom integration required for traceability | Native — Jira issue input → test cases → bidirectional sync via TestQuality |
| GitHub CI/CD Integration | None — manual sessions cannot trigger on PR events | CI trigger only — runs pre-written scripts on pipeline event | PR-aware — autonomous exploration triggers on every pull request via TestQuality |
| Defect Escalation Cost | High — discovery lag increases remediation cost significantly | Medium — known paths caught early, unknowns escape to production | Low — continuous pre-merge discovery flattens the escalation cost curve |
| Scales With Release Velocity | Requires headcount — coverage drops as sprint pace increases | Partially — execution scales but script authoring does not | Yes — generation, execution and maintenance all autonomous |
The reallocation effect compounds over time. Engineering teams that eliminated script maintenance overhead in Q1 2025 reported deploying two to three additional feature cycles per quarter by Q4 — not because they hired more engineers, but because they stopped assigning senior QA talent to updating brittle selectors after every UI change.
Key Takeaway for Managers: Autonomous testing is not a quality upgrade — it is a cost-reduction strategy with a quality byproduct. The transition from script maintenance to agent orchestration recovers engineering capacity that was previously invisible as overhead.
How Does Autonomous Exploration Integrate With GitHub and Jira Without Disrupting Existing Pipelines?
Autonomous exploratory agents integrate with GitHub Actions and Jira through event-driven triggers — no pipeline restructuring required. An agent run initiates on pull request creation, executes against the feature branch’s staging environment, and delivers structured findings as GitHub Issues or Jira tickets before the code review begins.
The integration architecture is deliberately non-invasive. Teams connect their GitHub repository and Jira project workspace to TestQuality, configure the agent’s entry point and authentication credentials for the staging environment, and define the severity thresholds that trigger automatic ticket creation. From that point forward, every push to a feature branch generates an autonomous exploration run in parallel with the existing CI suite.
Within the TestQuality dashboard, exploration run results appear alongside manually authored test cases — giving QA leads a unified view of scripted coverage and agent-discovered findings without switching contexts. Defects escalated by the agent arrive in Jira with the full evidence package: reproduction steps, network waterfall, visual diff, and the specific application state path that exposed the failure. Developers receive actionable context immediately, without waiting for a QA engineer to triage and document the finding manually.
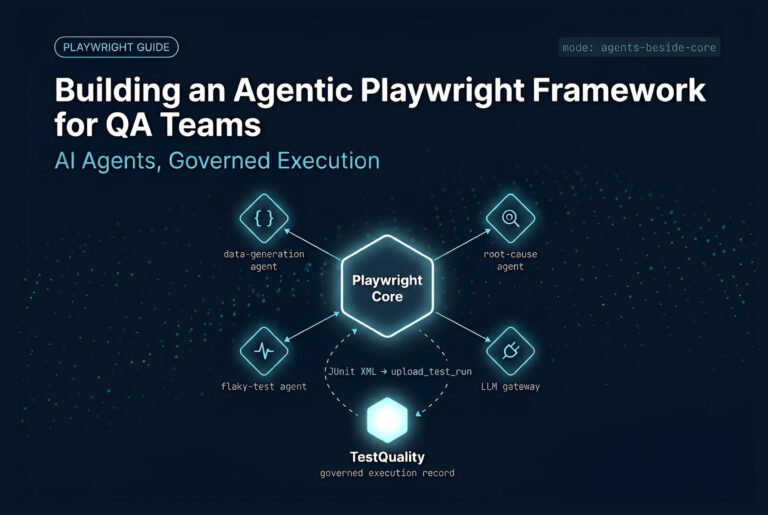
Beyond AI-generated test coverage, TestQuality provides a native Exploratory Testing feature for teams named “Explorations”, that need structured human-led ad-hoc testing alongside their automated workflows. Rather than leaving unscripted human sessions undocumented, Explorations gives testers a named session container — with a defined mission, milestone link, real-time log entries, pass/fail status tracking, and screenshot attachments — all recorded inside the same TestQuality platform where AI-generated test cases from TestStory.ai are executed and tracked. Critically, when a tester identifies a defect during an exploration session, they can log it directly from the log entry via the three-dot menu — and if a GitHub or Jira integration is active, that defect is created instantly as an issue in the connected repository without leaving TestQuality. The result is a unified quality record that captures both what the agent discovered autonomously and what the human tester found through intuition-driven investigation — every finding traceable, every defect routed, in a single testing history linked to the originating milestone.
Key Takeaway for Managers: The most common adoption barrier for autonomous testing is the assumption that it requires a separate toolchain. With native GitHub and Jira integration through TestQuality, the agent becomes an additional contributor to workflows already in place — and the Explorations feature ensures that human-led testing sessions are captured in the same record, not lost in a separate tool.
Technical Deep Dive FAQ
What is autonomous exploratory testing?
How is autonomous exploratory testing different from traditional test automation?
Can AI agents perform exploratory testing without a requirement document?
How does agentic exploration differ from traditional fuzzing or monkey testing?
What is the ROI of autonomous exploration compared to manual QA sessions?
Does autonomous exploratory testing replace human QA engineers?
How do autonomous agents navigate complex authentication and multi-step workflows?
What infrastructure is required to implement agentic exploratory testing?
Key Takeaways
What QA Leadership Needs to Act On in 2026
The shift from script execution to autonomous exploration is not a roadmap item — it is a current competitive reality.
Unknown unknowns are the primary defect risk: The failures that reach production emerge from undocumented state intersections — not from features that were tested in isolation. Only curiosity-driven agents without human assumptions systematically surface them.
Speed differential is structural, not marginal: Autonomous agents scan 1,000+ edge-case permutations in the time a human tester evaluates a single happy path. The coverage gap compounds with every release cycle.
Visual diffing closes the DOM blind spot: A critical UI element can be present in the HTML and simultaneously inaccessible to users. DOM-based test assertions miss this class of failure entirely. Multimodal agents catch it on every exploration run.
Script maintenance is a recoverable cost: Legacy automation frameworks consume approximately 25-30% of QA sprint capacity in maintenance overhead. Autonomous agents eliminate this overhead — and IBM’s foundational research confirms that earlier defect discovery reduces remediation cost by up to 100x.
Integration requires no pipeline restructuring: Native GitHub Actions triggers and Jira ticket creation through TestQuality mean autonomous exploration extends existing workflows rather than replacing them — defect findings arrive in the same backlog developers already manage.
Human QA engineers are elevated, not replaced: The transition shifts senior QA talent from script maintenance and manual session execution to strategic architecture — designing what agents explore, interpreting findings, and directing quality outcomes across the full release cycle.
“Autonomous exploration does not validate what you planned — it discovers what you missed. In 2026, that distinction became the difference between resilient software and escaped production failures.”
Start Free Today
Transition from script-writing to outcome-orchestration.
TestStory.ai generates structured test cases from your user stories, acceptance criteria, or architecture diagrams — then syncs them directly into TestQuality for execution, tracking, and team collaboration.
✦ Get 500 TestStory.ai credits every month included with your TestQuality subscription — no extra cost.
Try TestStory.ai Free → Start TestQuality Free →No credit card required on either platform.